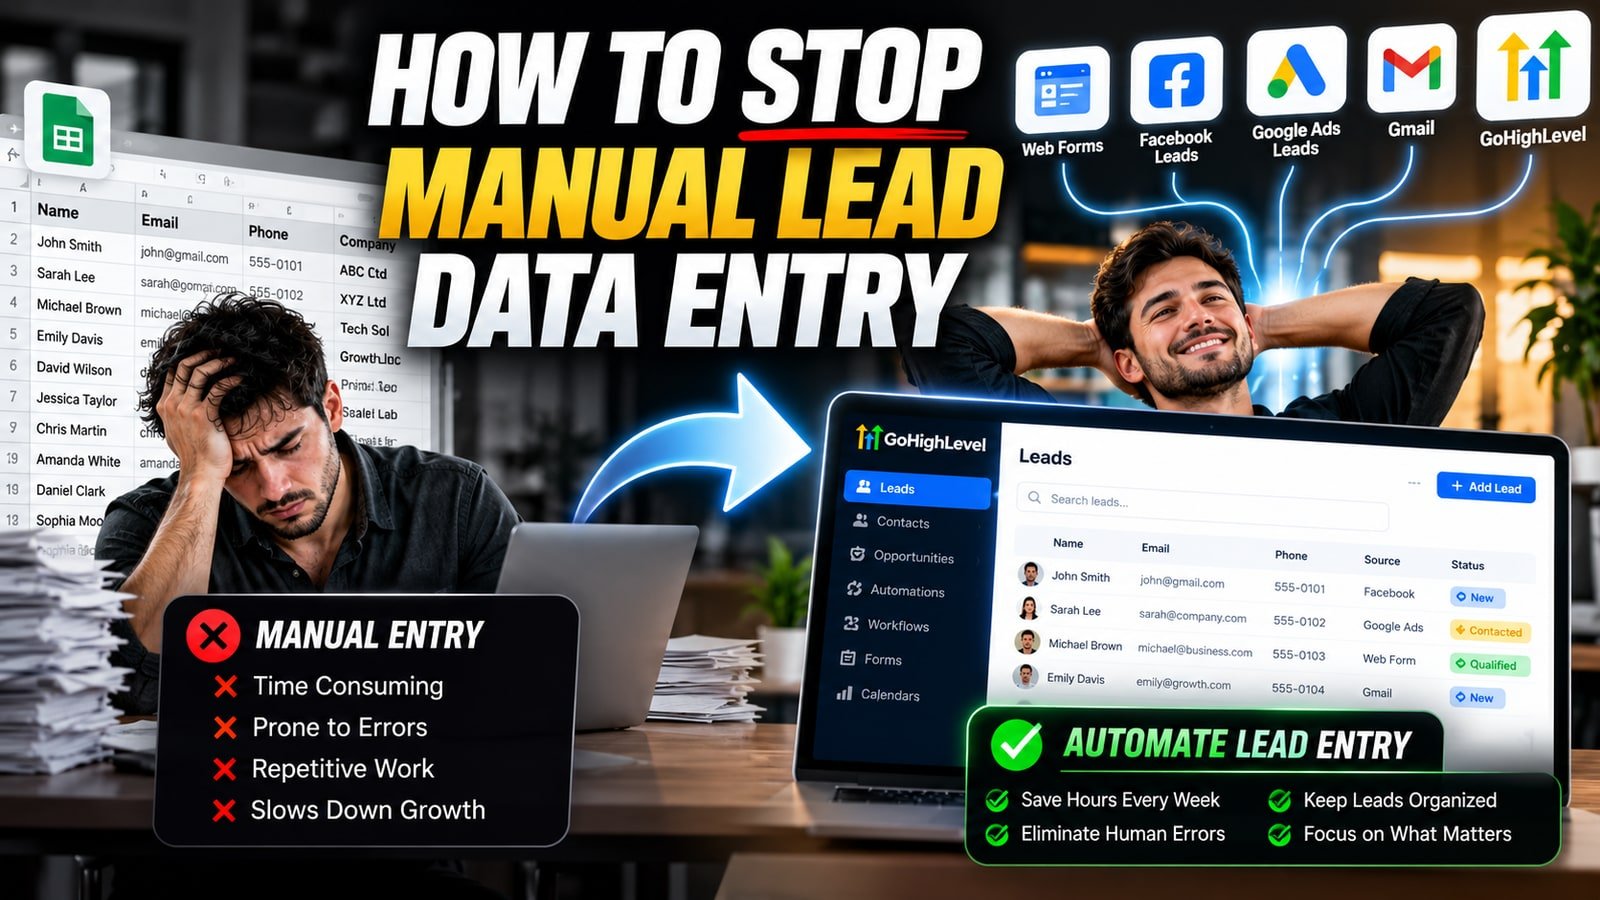
Manual lead data entry is almost never a discipline problem, which is why telling the team to be better about it does not work. It happens because leads arrive in six different shapes through six different channels and the CRM only accepts one, so somebody becomes the translation layer. Stopping it means removing the need to translate, not working faster at it. This is the order to do that in, including the parts that are genuinely not worth automating.
Key takeaways
- Manual lead data entry is caused by having many unconnected channels, not by a bad CRM or a careless team — a business with one lead source rarely has this problem.
- Salesforce's 2026 State of Sales report, surveying 4,050 sales professionals, found the average seller spends 40% of their time selling and names manual data entry among the non-selling work consuming the rest.
- Harvard Business Review's 2011 audit of 2,241 US companies found contact within an hour made a lead nearly seven times likelier to qualify than an hour later — fifteen years old now, so a direction rather than a current multiplier.
- Fix the order, not the speed: one front door for every channel, then structured capture at the source, then matching and routing on entry.
- Prefer a native integration over a webhook, a webhook over a scheduled import, and model extraction only where there is genuinely no structure to capture.
- Records created by extraction should be marked unconfirmed and must never overwrite a field a person has already verified.
- Leave the long tail alone. A channel producing two leads a month is not worth an automation that will break silently, and automating an ambiguous process only makes the ambiguity faster.
Why you are retyping leads in the first place
Count the ways a lead can reach you. A website form. A phone call. A reply to a cold email. A direct message on Instagram or LinkedIn. A lead form inside a Facebook or Google ad. A referral forwarded by a partner. Someone walking in. A spreadsheet from an event.
Each of those arrives in a different shape. The form gives you clean fields. The phone call gives you a voicemail and a scribbled name. The ad platform gives you a CSV you have to go and fetch. The DM gives you a first name and no email at all. The CRM wants the same eleven fields from every one of them, and the gap between those two facts is the job your team is doing by hand.
This is why buying a better CRM rarely fixes it. The CRM is not the bottleneck; the number of unconnected front doors is. A business with one lead channel almost never has a data entry problem. A business with seven always does, regardless of what it is running.
It is worth writing the list down before changing anything, with the rough volume beside each. Most teams find two or three channels account for the large majority of leads and the rest are a long tail. That list decides where the work goes, and it is usually a surprise to whoever maintains the CRM.
What the retyping actually costs
The obvious cost is time, and there is credible evidence it is substantial. Salesforce's State of Sales report, based on a survey of 4,050 sales professionals across 22 countries conducted in August and September 2025, found the average seller spends 40% of their time actually selling — the other 60% going to non-selling work, with manual data entry named specifically. That is Salesforce's own research into a problem Salesforce sells software to solve, so read it with that in mind, but the direction matches what most teams will recognize.
The larger cost is delay, and it is the one that shows up in revenue. The often-cited study here is from Harvard Business Review in March 2011, which audited 2,241 US companies and found that firms attempting contact within an hour of an inquiry were nearly seven times as likely to qualify the lead as those that tried just an hour later, and more than sixty times as likely as those who waited a day. That research is now fifteen years old and buyer behavior has moved since, almost certainly toward less patience rather than more — treat it as a well-evidenced direction rather than a current multiplier.
The point either way is that a lead sitting in an inbox waiting to be typed into a CRM is not a lead anyone is working. If the person who does the typing is also the person who takes calls, the queue builds during exactly the hours that matter.
The third cost is the quietest. Typed data is wrong at a low but steady rate — a transposed digit in a phone number, an email with a missing letter, the same person entered twice under two spellings. Nobody notices a single bad record. Everybody notices eighteen months later when the database cannot be segmented and a reactivation campaign bounces.
Connecting the channels, matching on entry and routing without anyone retyping is what CRM automation covers — scoped to the channels you actually have rather than all of them.
Step one: give every lead one front door
Before automating any capture, reduce the number of places a lead can land. This is unglamorous and it is the step that makes everything after it cheap.
In practice that means every channel terminating in the same system rather than in somebody's personal inbox or phone. Ad platform lead forms connected to the CRM directly rather than downloaded. The contact form posting to the CRM rather than emailing the office address. Calls going through a tracked business number rather than a salesperson's mobile. Shared inboxes rather than individual ones for anything inbound.
The test is simple: if a lead arrived while the person who normally handles it was on holiday, would it still be visible to someone else? Every channel where the answer is no is a channel that will produce manual entry forever, because the data is landing somewhere private.
Expect resistance on the phone number specifically. Salespeople often prefer their own mobile, and the trade is real — but a call to a personal phone is invisible to the business, and every one of them becomes a record somebody types later from memory, if at all.
- Website and landing page forms post directly into the CRM, not to an email address.
- Ad platform lead forms connect natively rather than being exported and imported.
- Inbound calls route through a tracked number so the call itself creates a record.
- Shared inbox for inbound email, not individual mailboxes.
- One owner for the list of channels, so new ones do not appear unannounced.
Step two: capture it structured, at the source
The cheapest data to work with is data that arrived in fields. Every layer you add between the person typing their details and the record in your CRM is a layer where something has to be interpreted, and interpretation is what costs money.
So the order of preference is fixed. A native integration between the source and the CRM beats everything, because the fields map once and then nobody touches them. Below that, a webhook or an automation platform moving the data on a trigger. Below that, a scheduled import. At the bottom, and only when nothing else is possible, extracting fields from free text with a model.
Most teams reach for the bottom of that list first because it feels like the clever solution, and it is the most fragile. Extraction from unstructured text works well, but it has a failure rate that a native field mapping does not, so it belongs where there is genuinely no structure to capture — not as a substitute for connecting two systems that already speak to each other.
While you are there, cut the form fields. Every field you ask for is a field somebody can mistype and a reason for a prospect to abandon. Capture the minimum that lets you respond, and get the rest in the conversation that follows. A clean record with four correct fields beats a complete one with eleven, two of which are wrong.
- Best: native integration — the source writes to the CRM directly.
- Good: webhook or automation platform firing on a trigger.
- Acceptable: scheduled import on a fixed interval.
- Last resort: a model extracting fields from free text.
- Always: fewer fields at capture, the rest gathered in conversation.
Step three: the channels that resist structure
Some leads will never arrive in fields. A phone call is audio. An inbound email is prose. A DM is three words and an emoji. These are the ones where manual entry survives longest, and they are where the current generation of tools genuinely helps.
For calls, the working pattern is transcription plus extraction: the call is recorded and transcribed, a model pulls out the name, the contact details, what the caller wanted and how urgent it sounded, and that becomes a draft record. For inbound email, the same shape — parse the message, propose the fields. For messaging channels, usually the honest answer is a short automated reply that asks for an email address, because without one there is no record worth keeping.
The critical design choice in all of this is draft versus done. A model reading a voicemail should create a record marked unconfirmed, not a clean one indistinguishable from a verified entry. Get that wrong and you have not removed the bad data, you have removed your ability to see which data is bad.
The same applies to overwriting. An extraction step should be allowed to fill an empty field and should not be allowed to overwrite one a human has confirmed. That single rule prevents the most common and most annoying failure, which is an automation quietly replacing a correct phone number with a worse one it found in a signature block.
Step four: deduplicate and enrich on the way in
Most teams clean the database periodically. The teams who do not have a data problem clean it at the moment of entry instead, which is the only point at which it is cheap.
A match check on the way in — against email first, then phone, then name with company — decides whether this is a new record or an existing one making contact again. That second case matters more than it sounds. Someone inquiring for the third time is a different sales conversation from a cold lead, and a system that creates a third duplicate record hides the one fact that should change how the call goes.
Enrichment belongs at the same moment and should be held to a lower standard of trust than what the person told you themselves. Appended company size, industry or location is useful for routing and segmentation and should be stored as what it is: inferred, not supplied. Keep the source of each field if your CRM allows it.
This is also the right place for routing. Once a record exists, has been matched against the database and has whatever enrichment you are using, the system has enough to assign it to the right person and start the clock on responding — which is the entire point of removing the manual step.
What is not worth automating
A few parts of this reliably cost more than they return, and skipping them is part of the answer rather than a compromise.
The long tail of channels is first. If a source produces two leads a month, connecting it properly can take a day of work and will break silently at some point. Have a person handle those, deliberately, and spend the effort on the channels that produce the volume. An automation nobody is watching that fires twice a month is worse than a known manual step.
Second is automating before standardizing. If two people on the team disagree about what counts as a qualified lead or which stage a new record starts in, that disagreement has to be settled by a human decision, not encoded by whoever happens to be building the automation. Automating an ambiguous process makes the ambiguity faster and much harder to see.
Third is auto-creating records from bulk sources. Scraped and purchased lists dumped into the CRM alongside genuine inquiries destroy the thing that makes the database useful, which is that a record in it means somebody actually expressed interest. Keep those separate, whatever the tool vendor suggests.
And fourth, do not automate the judgment call about whether a lead is worth pursuing. Scoring and sorting, yes. Discarding, no — not until the scoring has run alongside a person long enough that you know what it throws away.
Doing it in about a month
The sequence matters more than the speed, because each step makes the next one smaller. Attempting the clever extraction work before consolidating the channels is the most common way this stalls.
Week one is observation only. List every channel, the rough monthly volume of each, and who currently types it in. Do not change anything. The list is almost always wrong in someone's head until it is written down, and the volumes decide the whole plan.
Week two: connect the highest-volume structured channel properly, end to end, and leave everything else alone. One channel done completely teaches you more about your own field mapping and duplicate rules than three done partially.
Week three: add match-on-entry and routing, so new records are checked against the database and land with an owner. Week four: take the messiest high-volume channel — usually the phone — and build the draft-record path for it, with unconfirmed records clearly marked.
At the end of that you will not have eliminated manual entry entirely, and that is the correct outcome rather than a failure. What you should have is a situation where the typing that remains is deliberate, confined to low-volume channels, and no longer sitting between an inquiry and somebody responding to it.
- Week 1 — list every channel, its volume, and who types it in. Change nothing.
- Week 2 — connect the highest-volume structured channel end to end.
- Week 3 — add duplicate matching and automatic routing on entry.
- Week 4 — build the draft-record path for the messiest high-volume channel.
- Ongoing — review what still gets typed each month and why.
Once records arrive clean and on their own, the seven automations worth running is what to build on top of them.
Related services
CRM Automation
We turn your CRM into an intelligent revenue engine — automated pipelines, smart follow-ups, AI scoring, and reporting that shows what to do next.
Explore crm intelligenceLead Generation
We build AI lead generation machines combining outbound prospecting, inbound capture, and intelligent scoring — delivering warm leads automatically.
Explore ai lead engine